Overview of Attack Methodology
$$ \left\lVert f_\theta(v + \delta, l) - y^\text{true} \right\rVert_2 \ge \tau,\quad \mathcal{D}(v, v + \delta) \le \varepsilon $$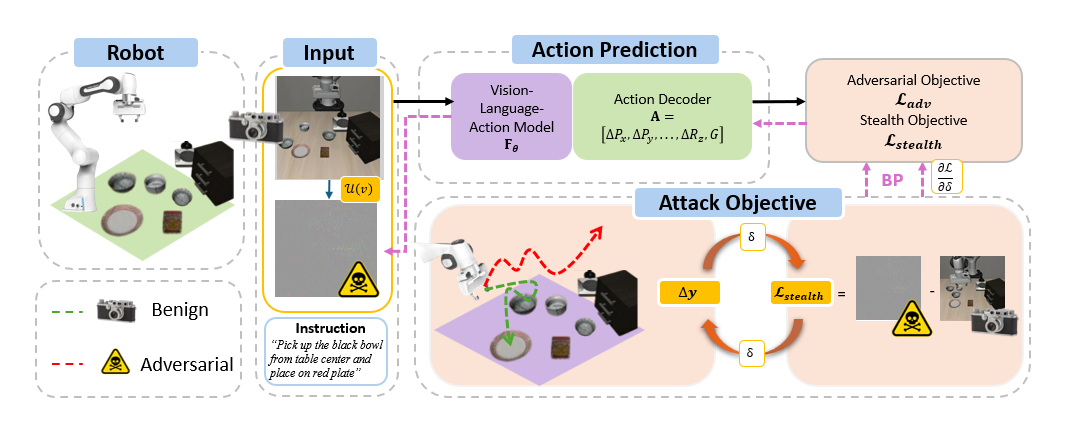
Here we see two objectives defined:
- The attack objective
$ \left\lVert f_\theta(v + \delta, l) - y^\text{true} \right\rVert_2 \ge \tau, $
- The Stealth objective
$ \mathcal{D}(v, v + \delta) \le \varepsilon$
Each objective are assigned with a threshold to define training optimal.
They are trained in an alternative optimization algorithm inspired by SPAA, the algorithm is heavily altered to adapted to the adversarial need of VLA attacker.
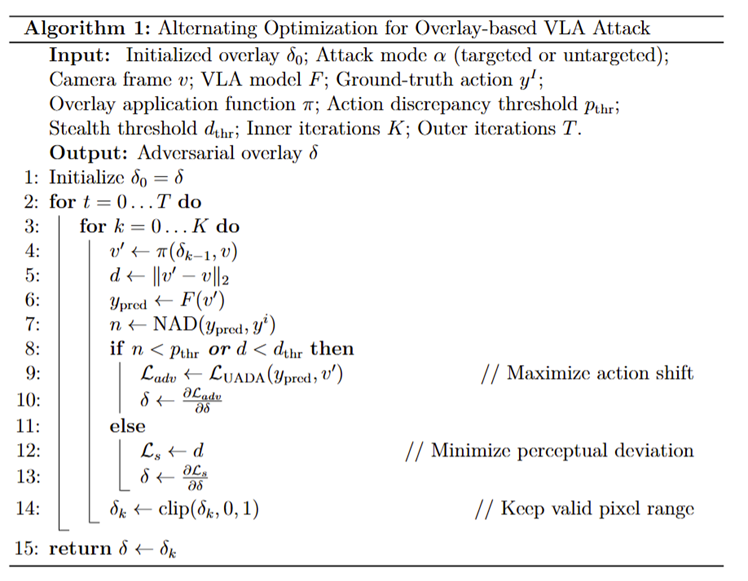
To understand more, you can check out my presentation or contact me at lusicheng@u.nus.edu
Simulation Experiment Result
UPL is applied to the LIBERO Spatial Suite, showing task failure due to discrepancy in action
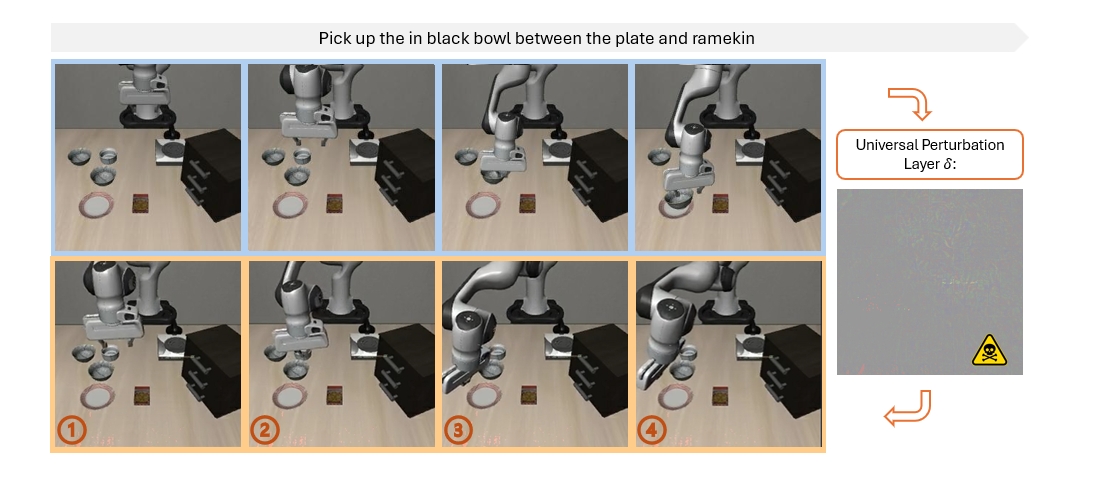
- d_thr = 15
- p_thr = 0.3
Supplementary Training Information Report
Photo with my senior
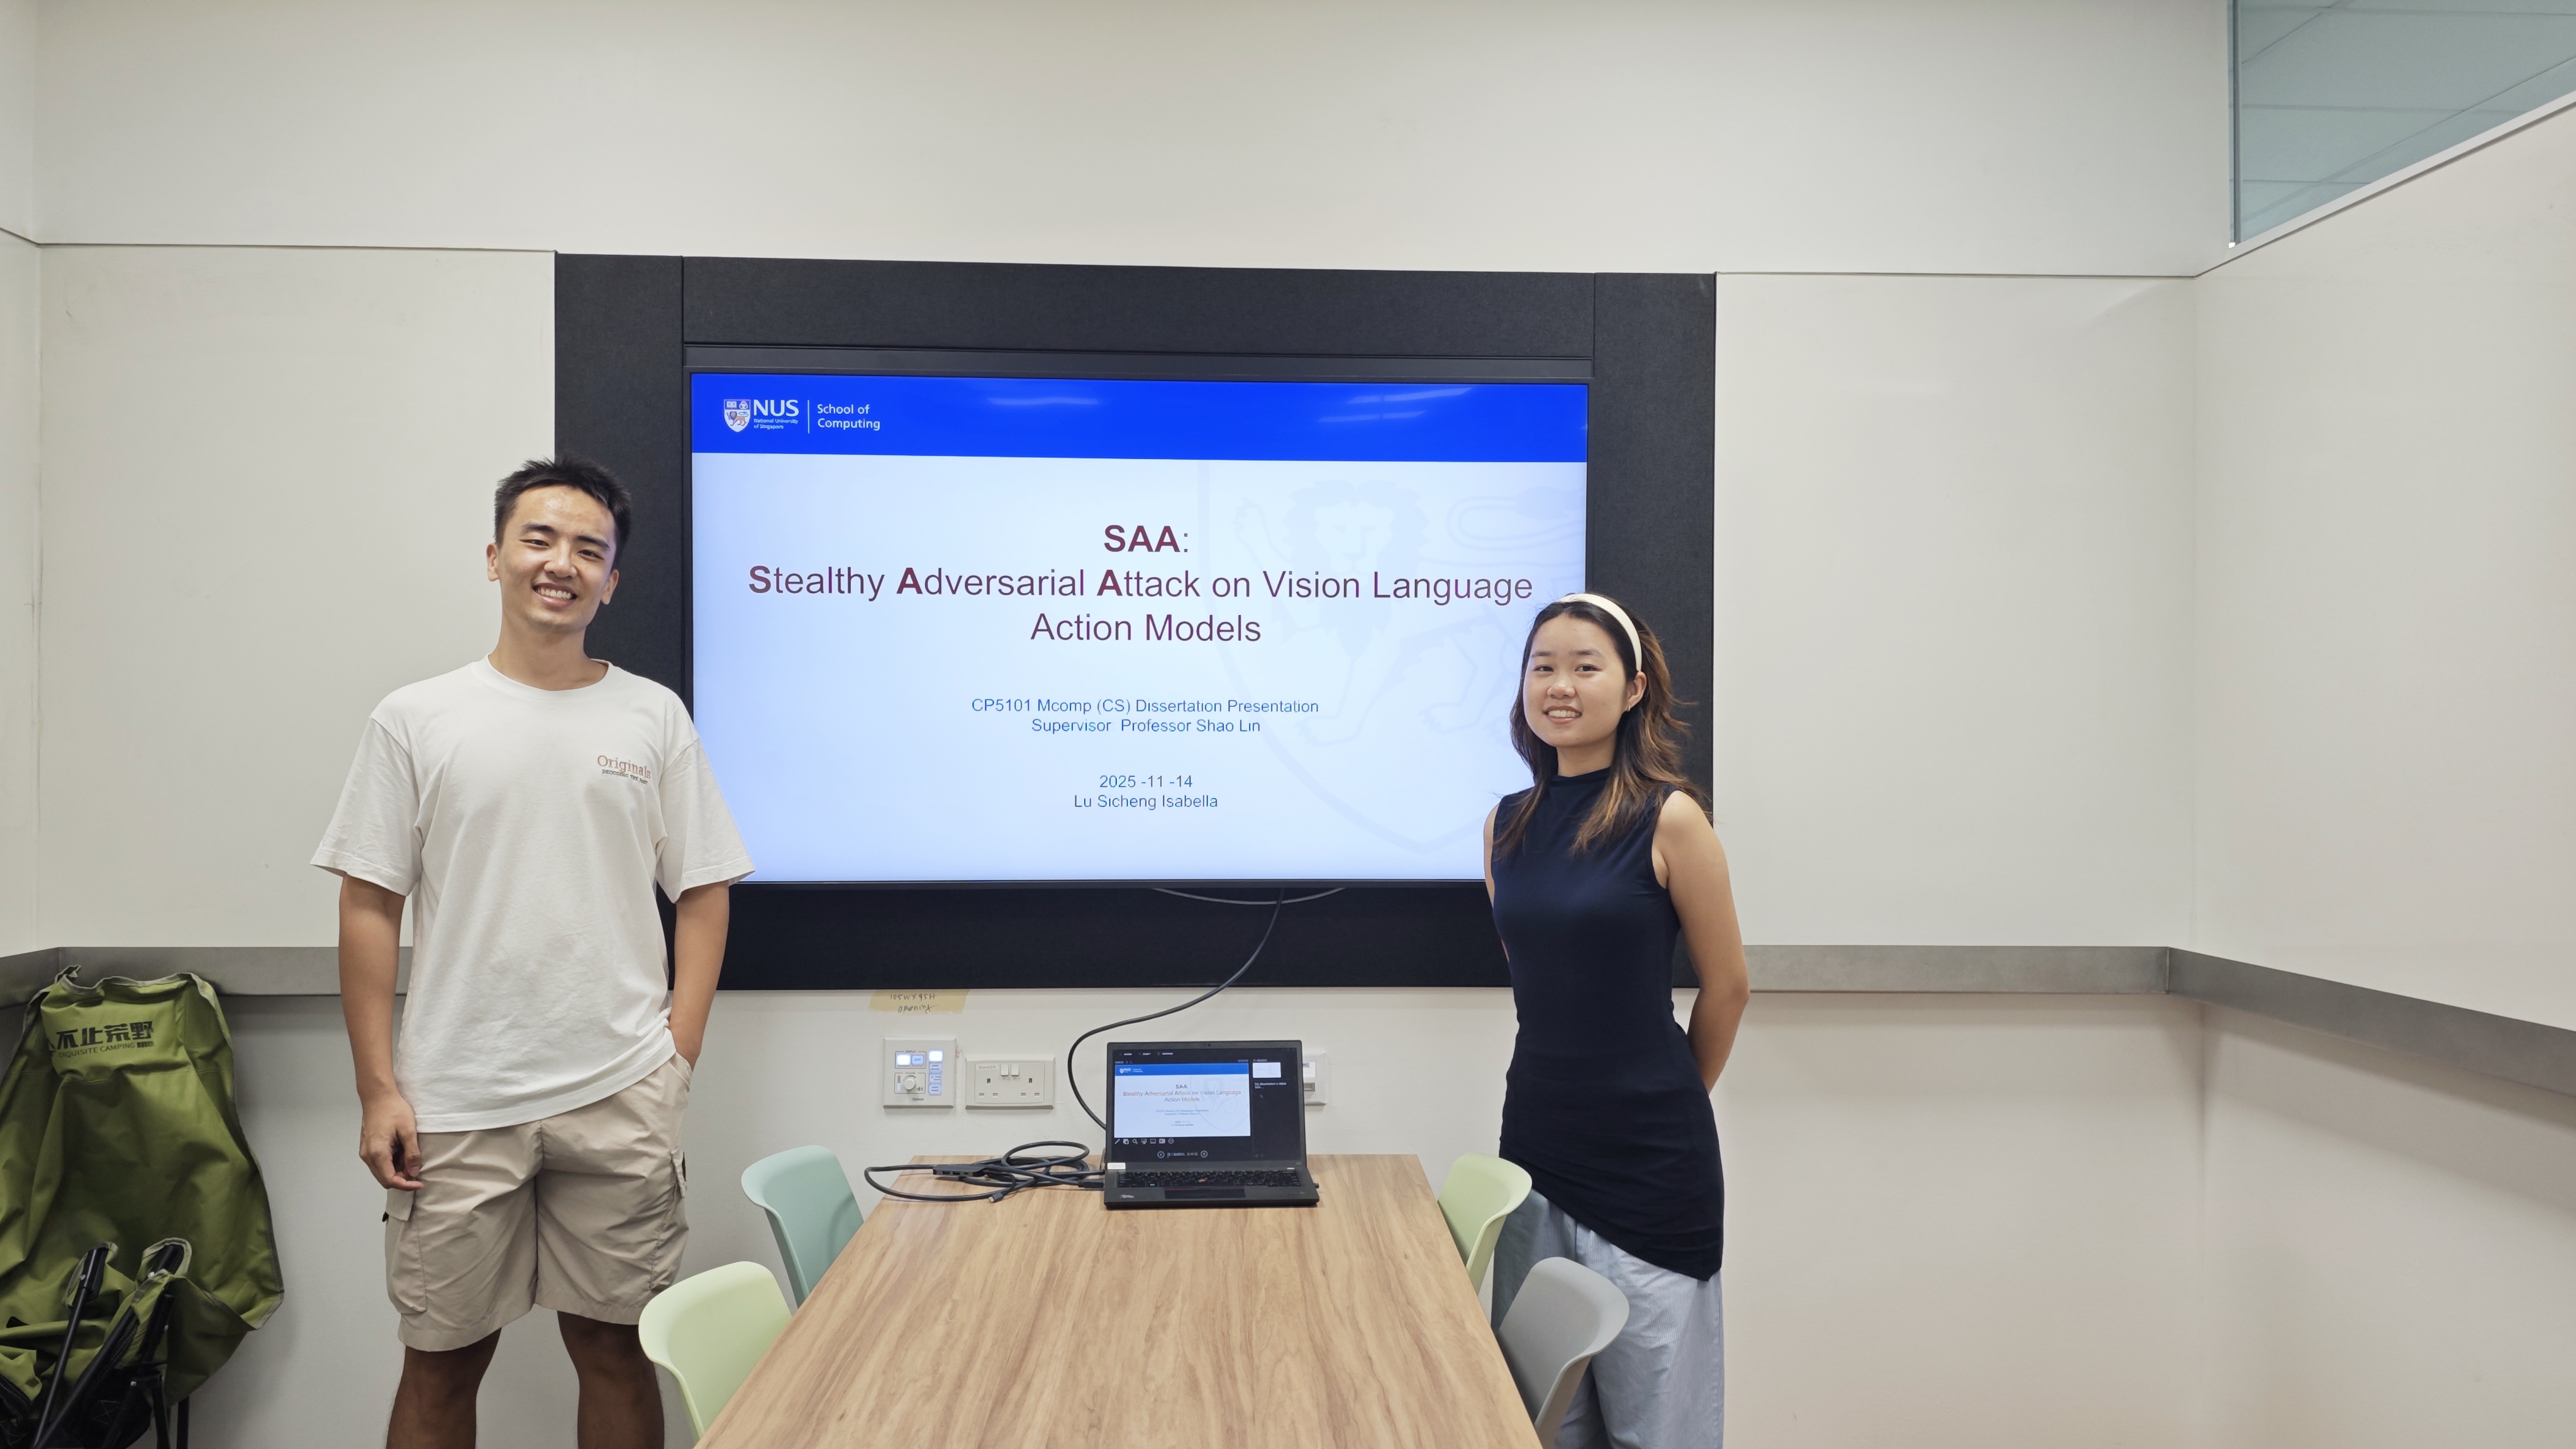
My supervisor Prof Shao assigned one of his all mighty PhD to provide some support. Turns out, Chongkai is one of the best mentor I ever had. I appreciate his guidance very very much.